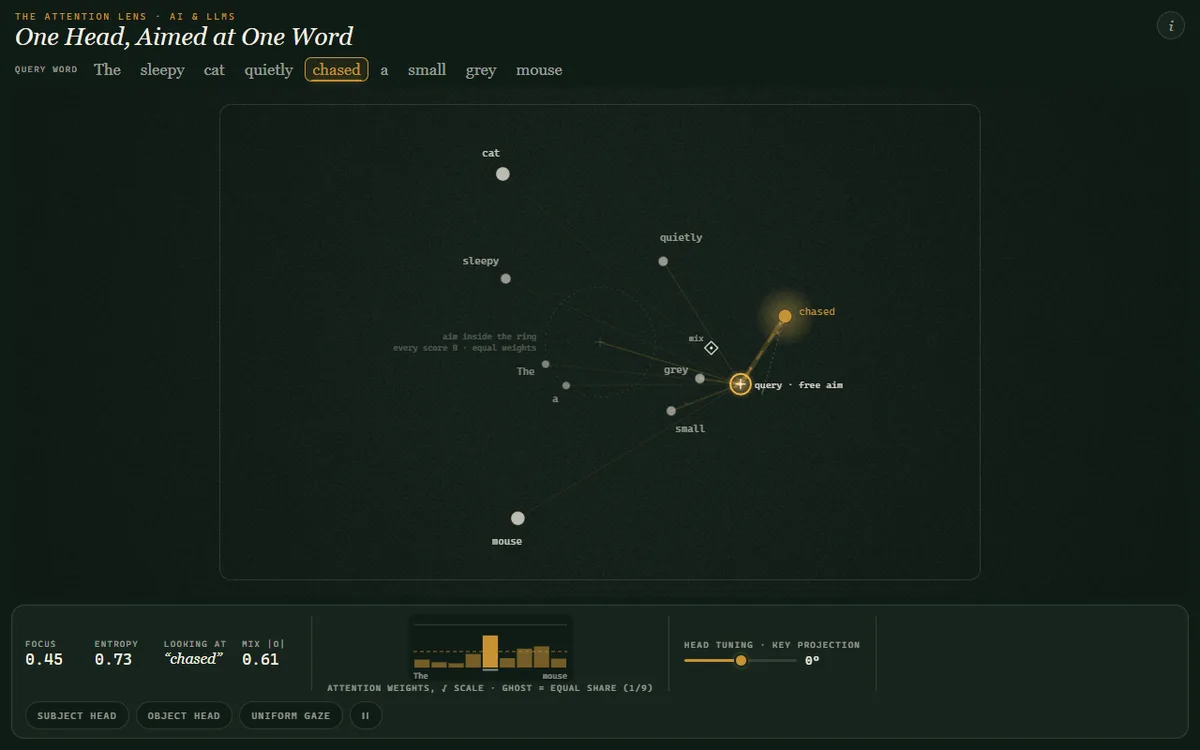
The Attention Lens
Aim one attention head's query over a word and watch the glowing threads sharpen onto a single focus or spread into an even gaze.
A self-contained deep dive — each class is a short illustrated explainer with narration, quick checks, an interactive, and a mastery quiz. Your progress saves automatically.
Labs in AI & LLMs
Aim one attention head's query over a word and watch the glowing threads sharpen onto a single focus or spread into an even gaze.
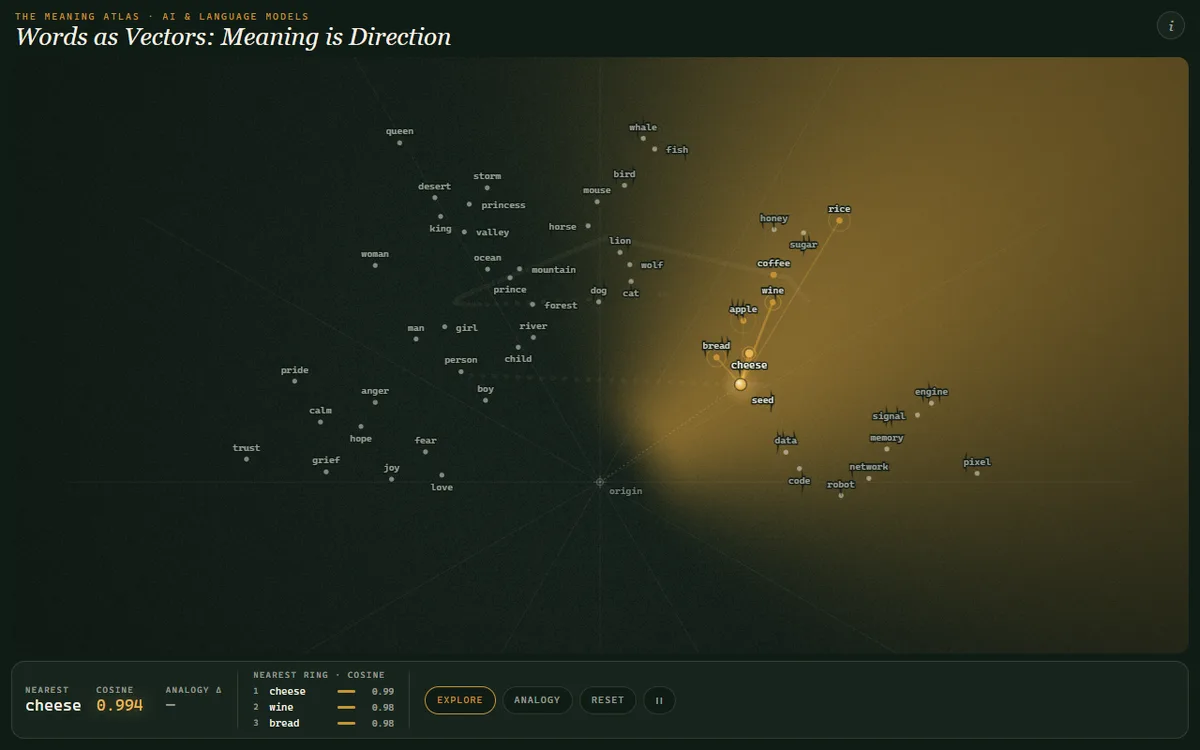
Drag a word through a semantic plane, then build king − man + woman with arrows and land on queen: analogies are literally arithmetic.
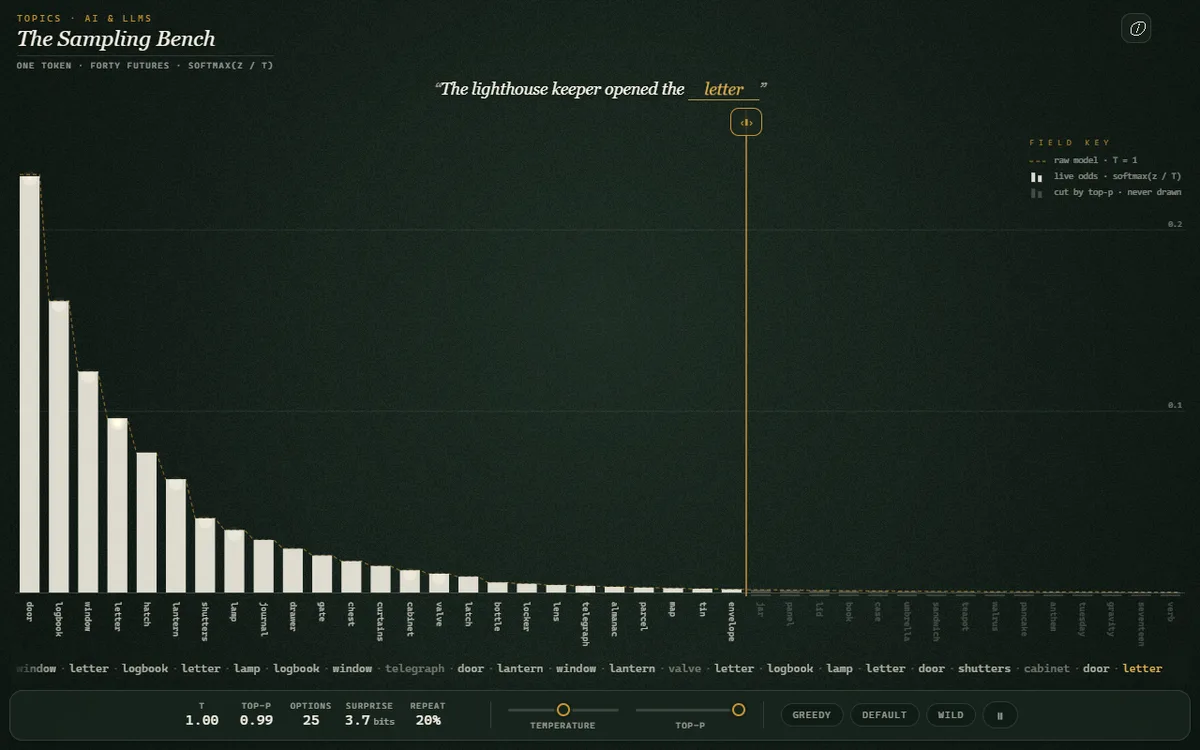
Sculpt a live next-token distribution with temperature and top-p, and watch the word stream go robotic, coherent, or unhinged.
 01
 02
 03
 04
 05
 06
 07
 08
 09
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
Every class is 13 cards · narrated film + illustration · 2 quick checks · an interactive · a 4-question mastery quiz. Nothing hidden — this is the complete text of How an LLM actually predicts the next word.
Welcome to class one. Most people interact with language models every day without knowing what's happening under the hood. ChatGPT, Claude, Gemini — they feel like magic. They are not. An LLM does exactly one thing: it predicts the next word. Or more precisely, the next token. That is the entire trick. Everything else you have ever seen an LLM do — answering questions, writing code, holding conversations, reasoning through problems — emerges from being incredibly good at that single task. Today we are going to peel back the layers and look at what actually happens when you press send. By the end, language models will stop being mysterious and start being a tool you can reason about clearly.
Every sentence ever written follows patterns. "The cat sat on the" almost always continues with "mat" or "floor." If a machine could learn those patterns, it could finish sentences. Then paragraphs. Then anything written.
Feed in some text. The model outputs a probability for every possible next token in its vocabulary. Higher probability means "this token is more likely to come next given what I've seen." That is the entire mechanism.
The idea of predicting the next word is old. What changed is how well we can do it. Each generation found better ways to capture context — and each better-capture-context unlocked new abilities.
Inside the model, every prediction goes through the same four steps. They run in milliseconds, but the architecture is the same every time.
Here is what really happens when you send a prompt. Take "The capital of France is." The tokenizer breaks it into five tokens — "The," space-"capital," space-"of," space-"France," space-"is." Notice the leading spaces are part of the tokens — that is how modern tokenizers handle word boundaries. The model processes those five token vectors through its transformer layers. At the output, it produces a probability for every single token in its vocabulary — about fifty thousand of them. The top result, with eighty-two percent probability, is space-"Paris." The next most likely is space-"the" at seven percent — maybe the model thinks the sentence might continue "is the most beautiful city." Then "Lyon" at one percent, hedging on a wrong but plausible French city. About forty-nine thousand nine hundred ninety-five other tokens get smaller and smaller probabilities. The model picks Paris because the probability is so dominant. That is one prediction step. Now the sequence becomes "The capital of France is Paris." The model runs again to predict what comes after Paris — probably a period, or maybe a comma, or maybe the word "and."
The most surprising thing about LLMs is that being good at next-token prediction turns out to require — and produce — an enormous amount of other skills.
When you watch ChatGPT or Claude type out a response word by word, that animation is not cosmetic. It is real. Each token genuinely requires a full forward pass through the model — typically about a hundred transformer layers, each with millions of parameters. On a fast model, that takes around fifty milliseconds. A two-hundred-token response takes about ten seconds end to end. Streaming is the practice of sending each token to your screen as soon as it is generated, instead of waiting for the whole response. It feels faster — you can start reading immediately — and it is faster, because the network round-trip happens in parallel with later token generation. When you understand that the typing animation is the actual generation process, you stop being impatient with it. You also stop being surprised when an LLM repeats itself or contradicts itself: it cannot "see ahead" to what it is about to write. It can only look back.
Once you accept that next-token prediction is the only mechanism, three implications follow that explain a lot of LLM behavior.
AI is bigger than language models. Knowing where LLMs fit explains what they are good at and what they are not.
These misconceptions show up everywhere — in news articles, in product pitches, in casual conversation. Naming them prevents bad decisions.
You do not have to take any of this on faith. The mechanism is open — you can inspect token probabilities and tokenization yourself.
Set aside ten minutes. Three small experiments will give you a permanent intuition for what is actually happening.
Six things to take away.